

Private Inference connects your own model endpoints to AI Gateway.
Enterprises running fine-tuned, self-hosted, or prerelease models used to need separate keys, client code, and logs for them. Those models can now run through the same authentication, SDKs and APIs, and observability as catalog models, so every model your team uses is managed in one place.
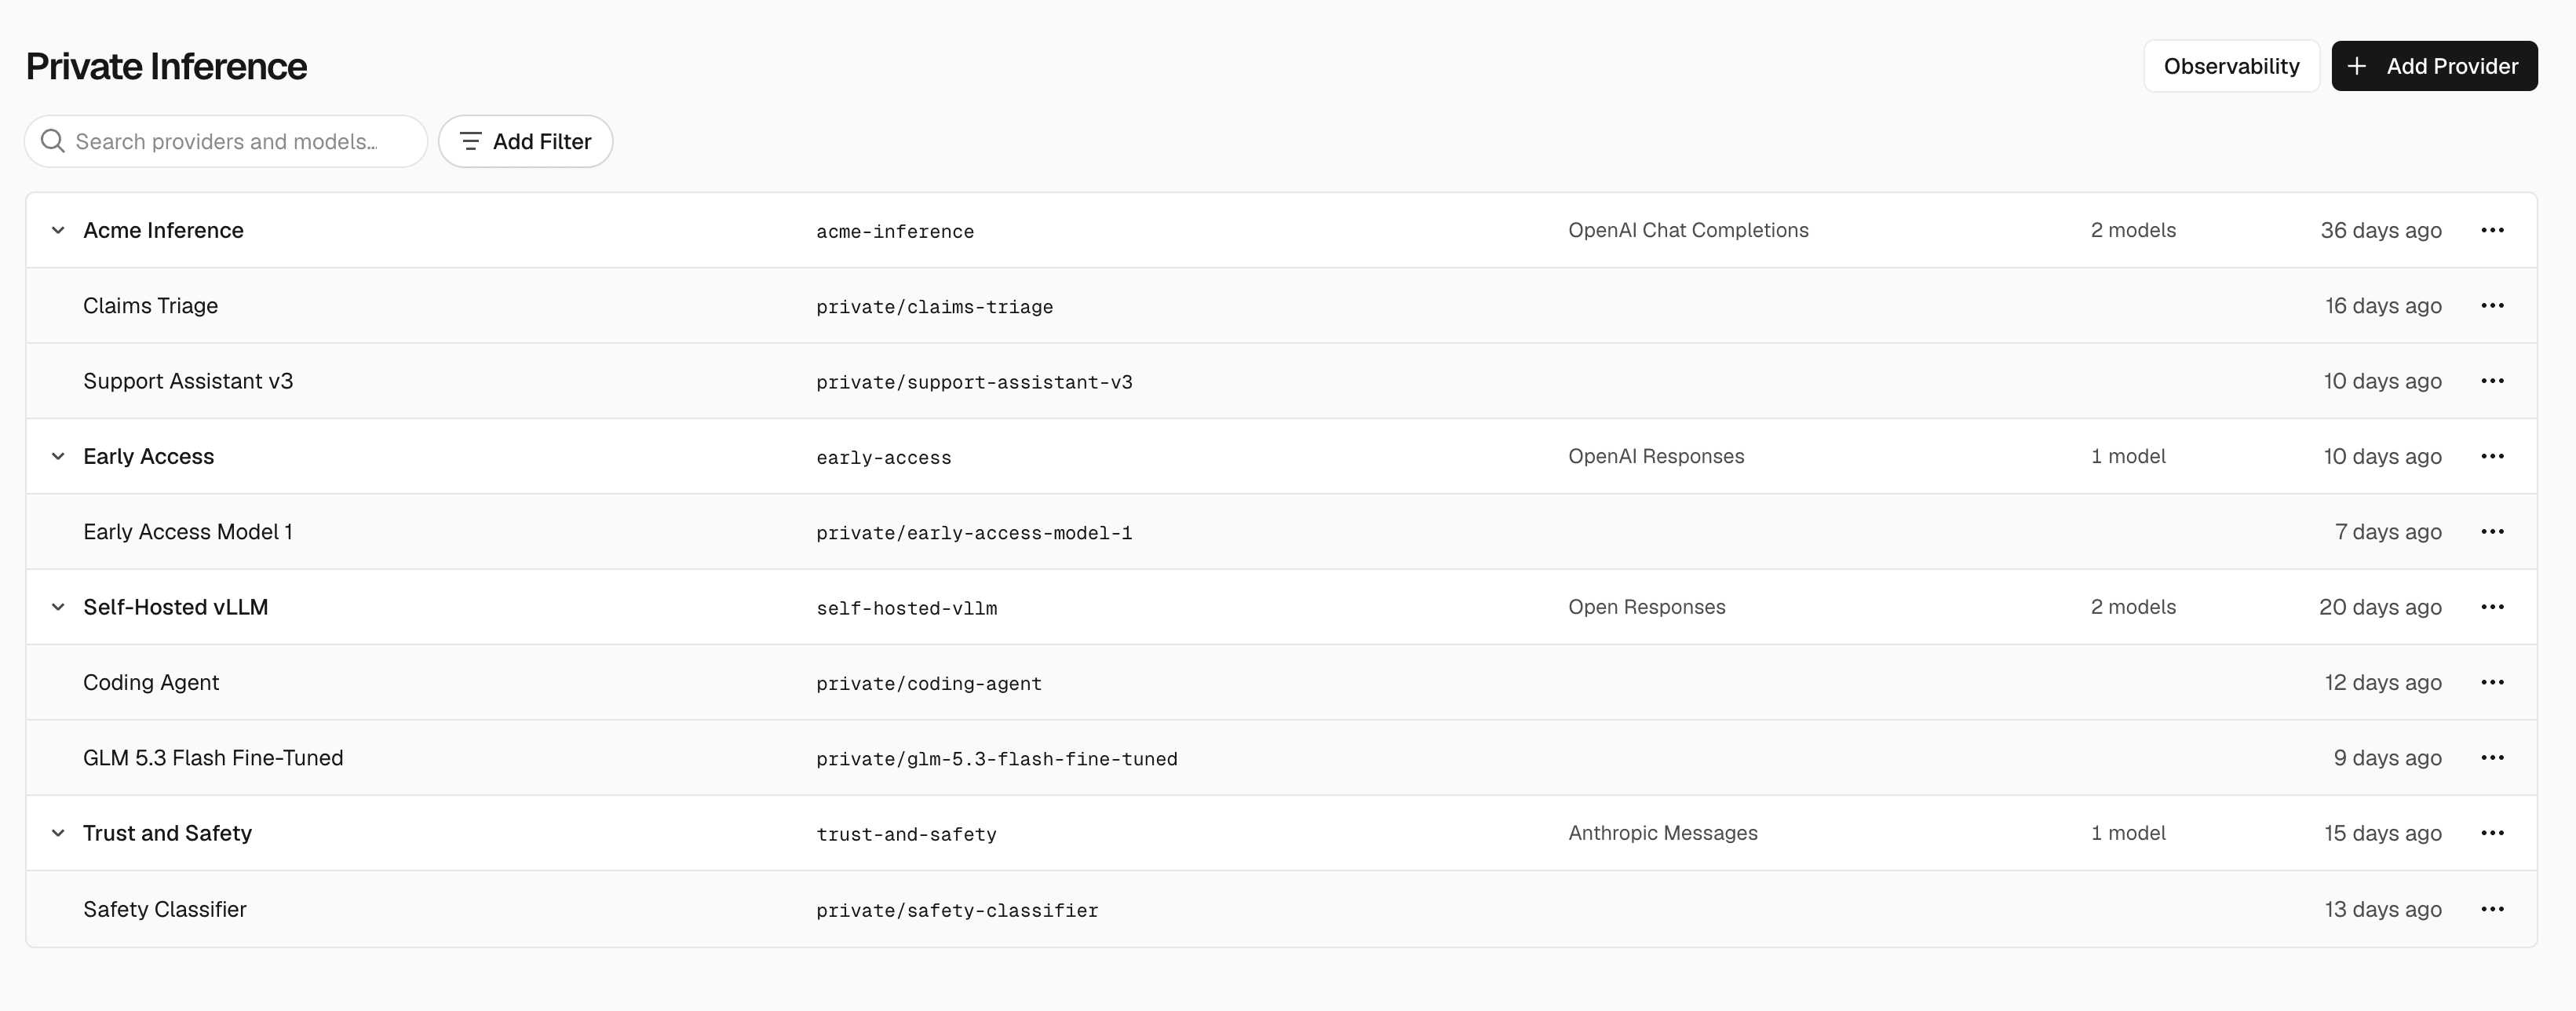
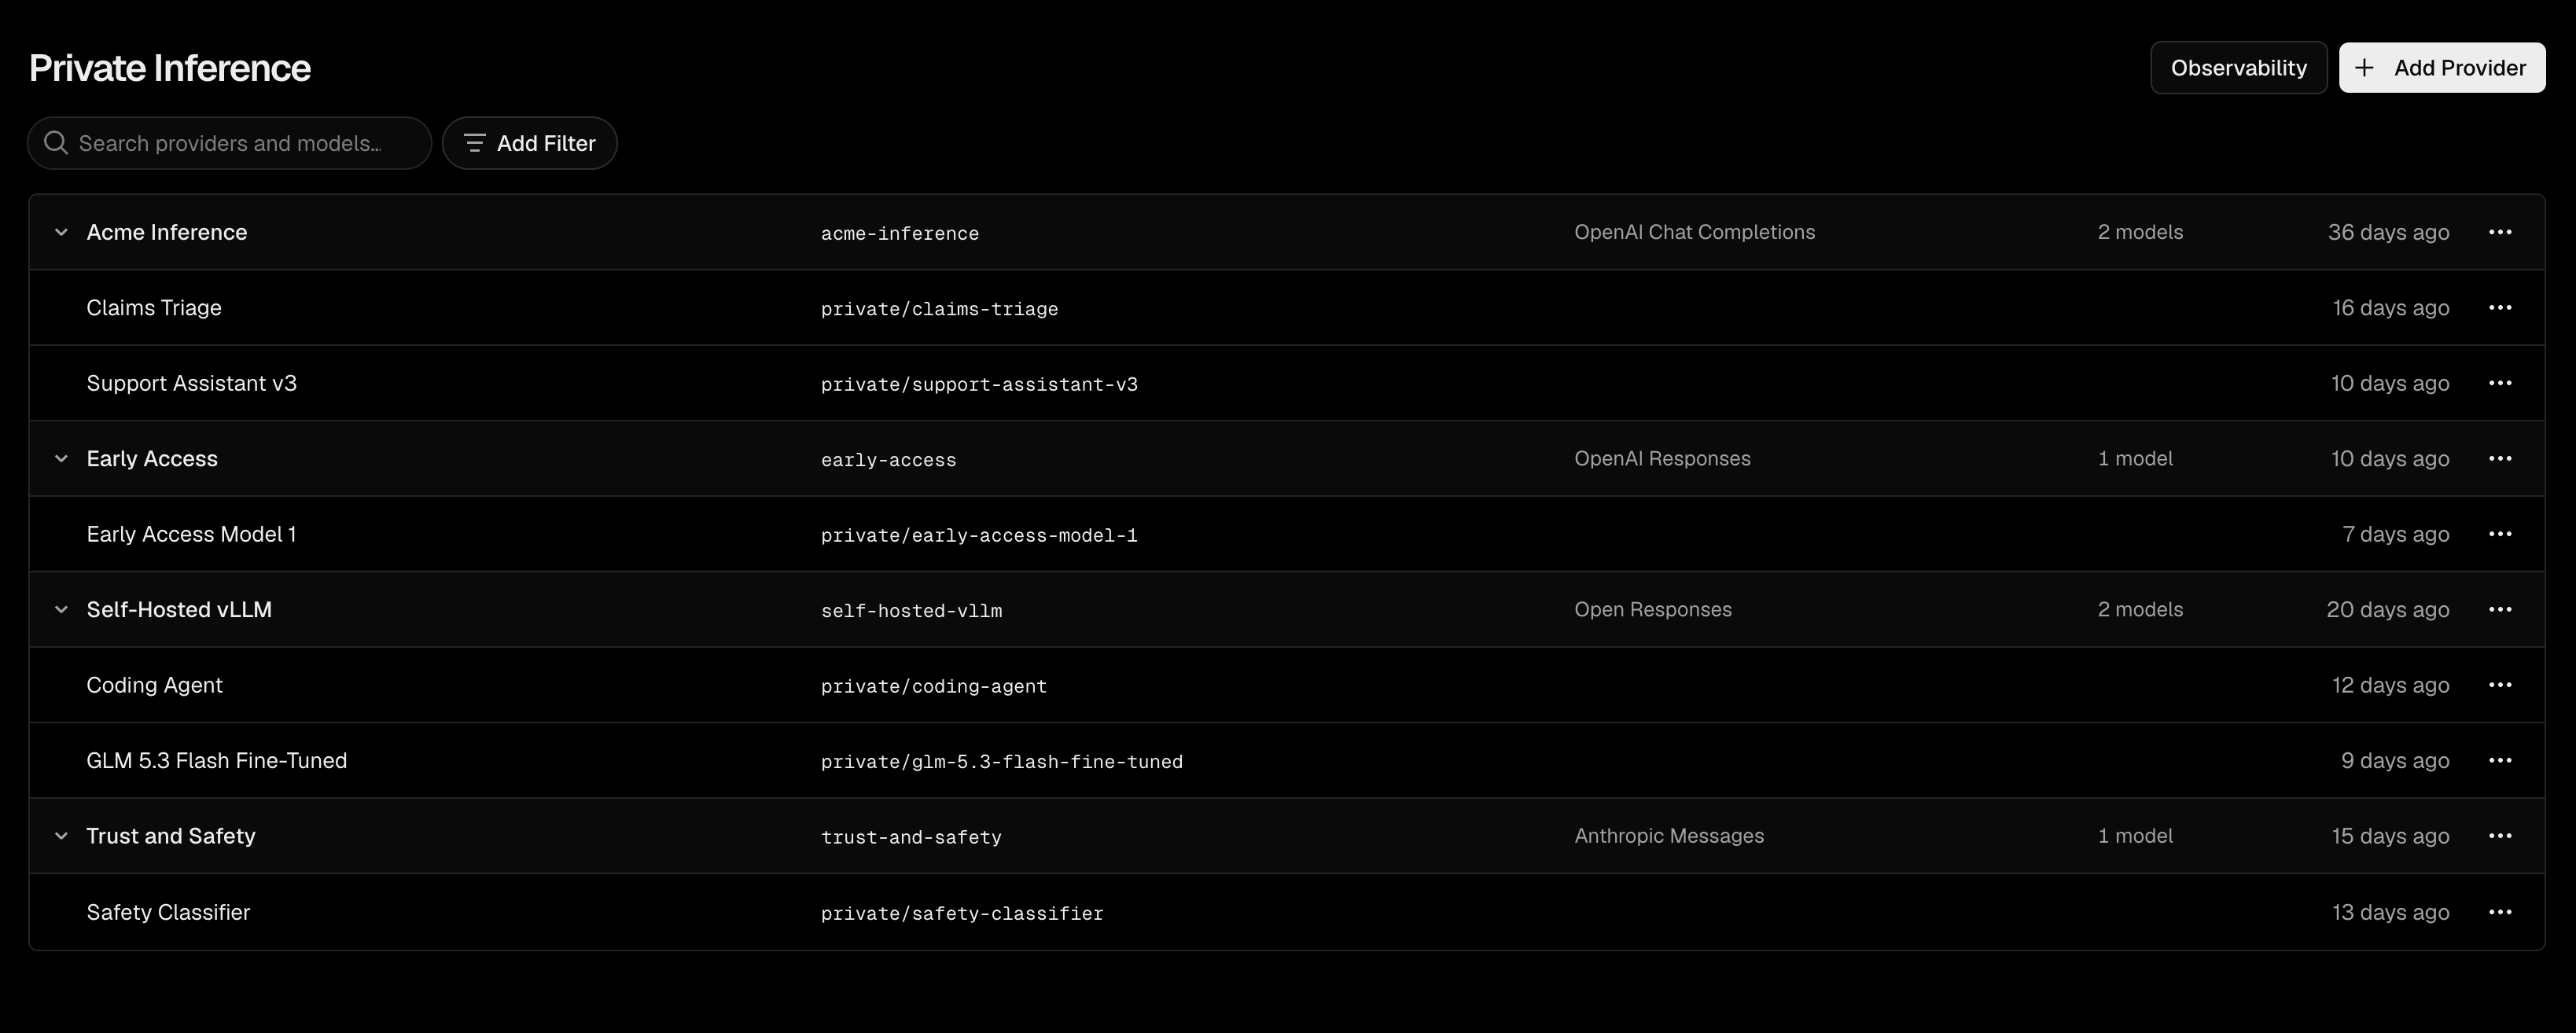
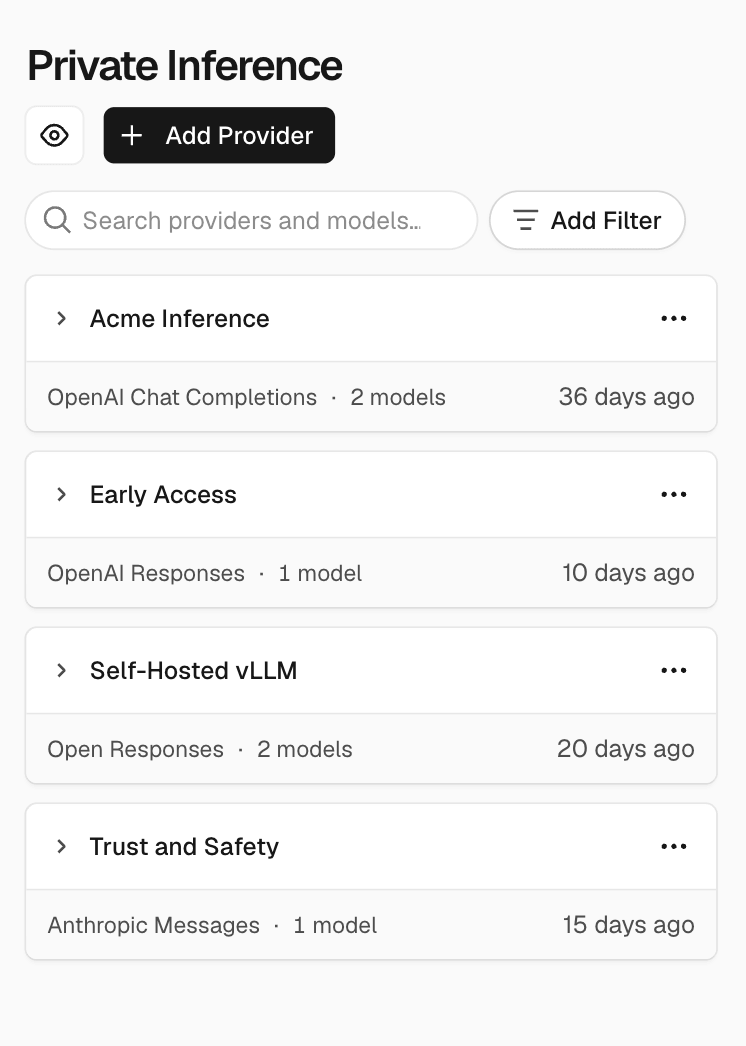
Use Private Inference to:
Switch between private and catalog models: Call private models through Chat Completions, Responses, or Messages. AI Gateway translates each request to your endpoint's format, so switching only changes the model ID.
Keep models scoped to your team: Only your Vercel team can view or call private models, and they aren't listed in the public catalog. Credentials are stored encrypted, and you can enable Zero Data Retention per provider.
Connect coding agents: Use private models in Claude Code, Codex, Cursor, and other coding agents connected to AI Gateway.
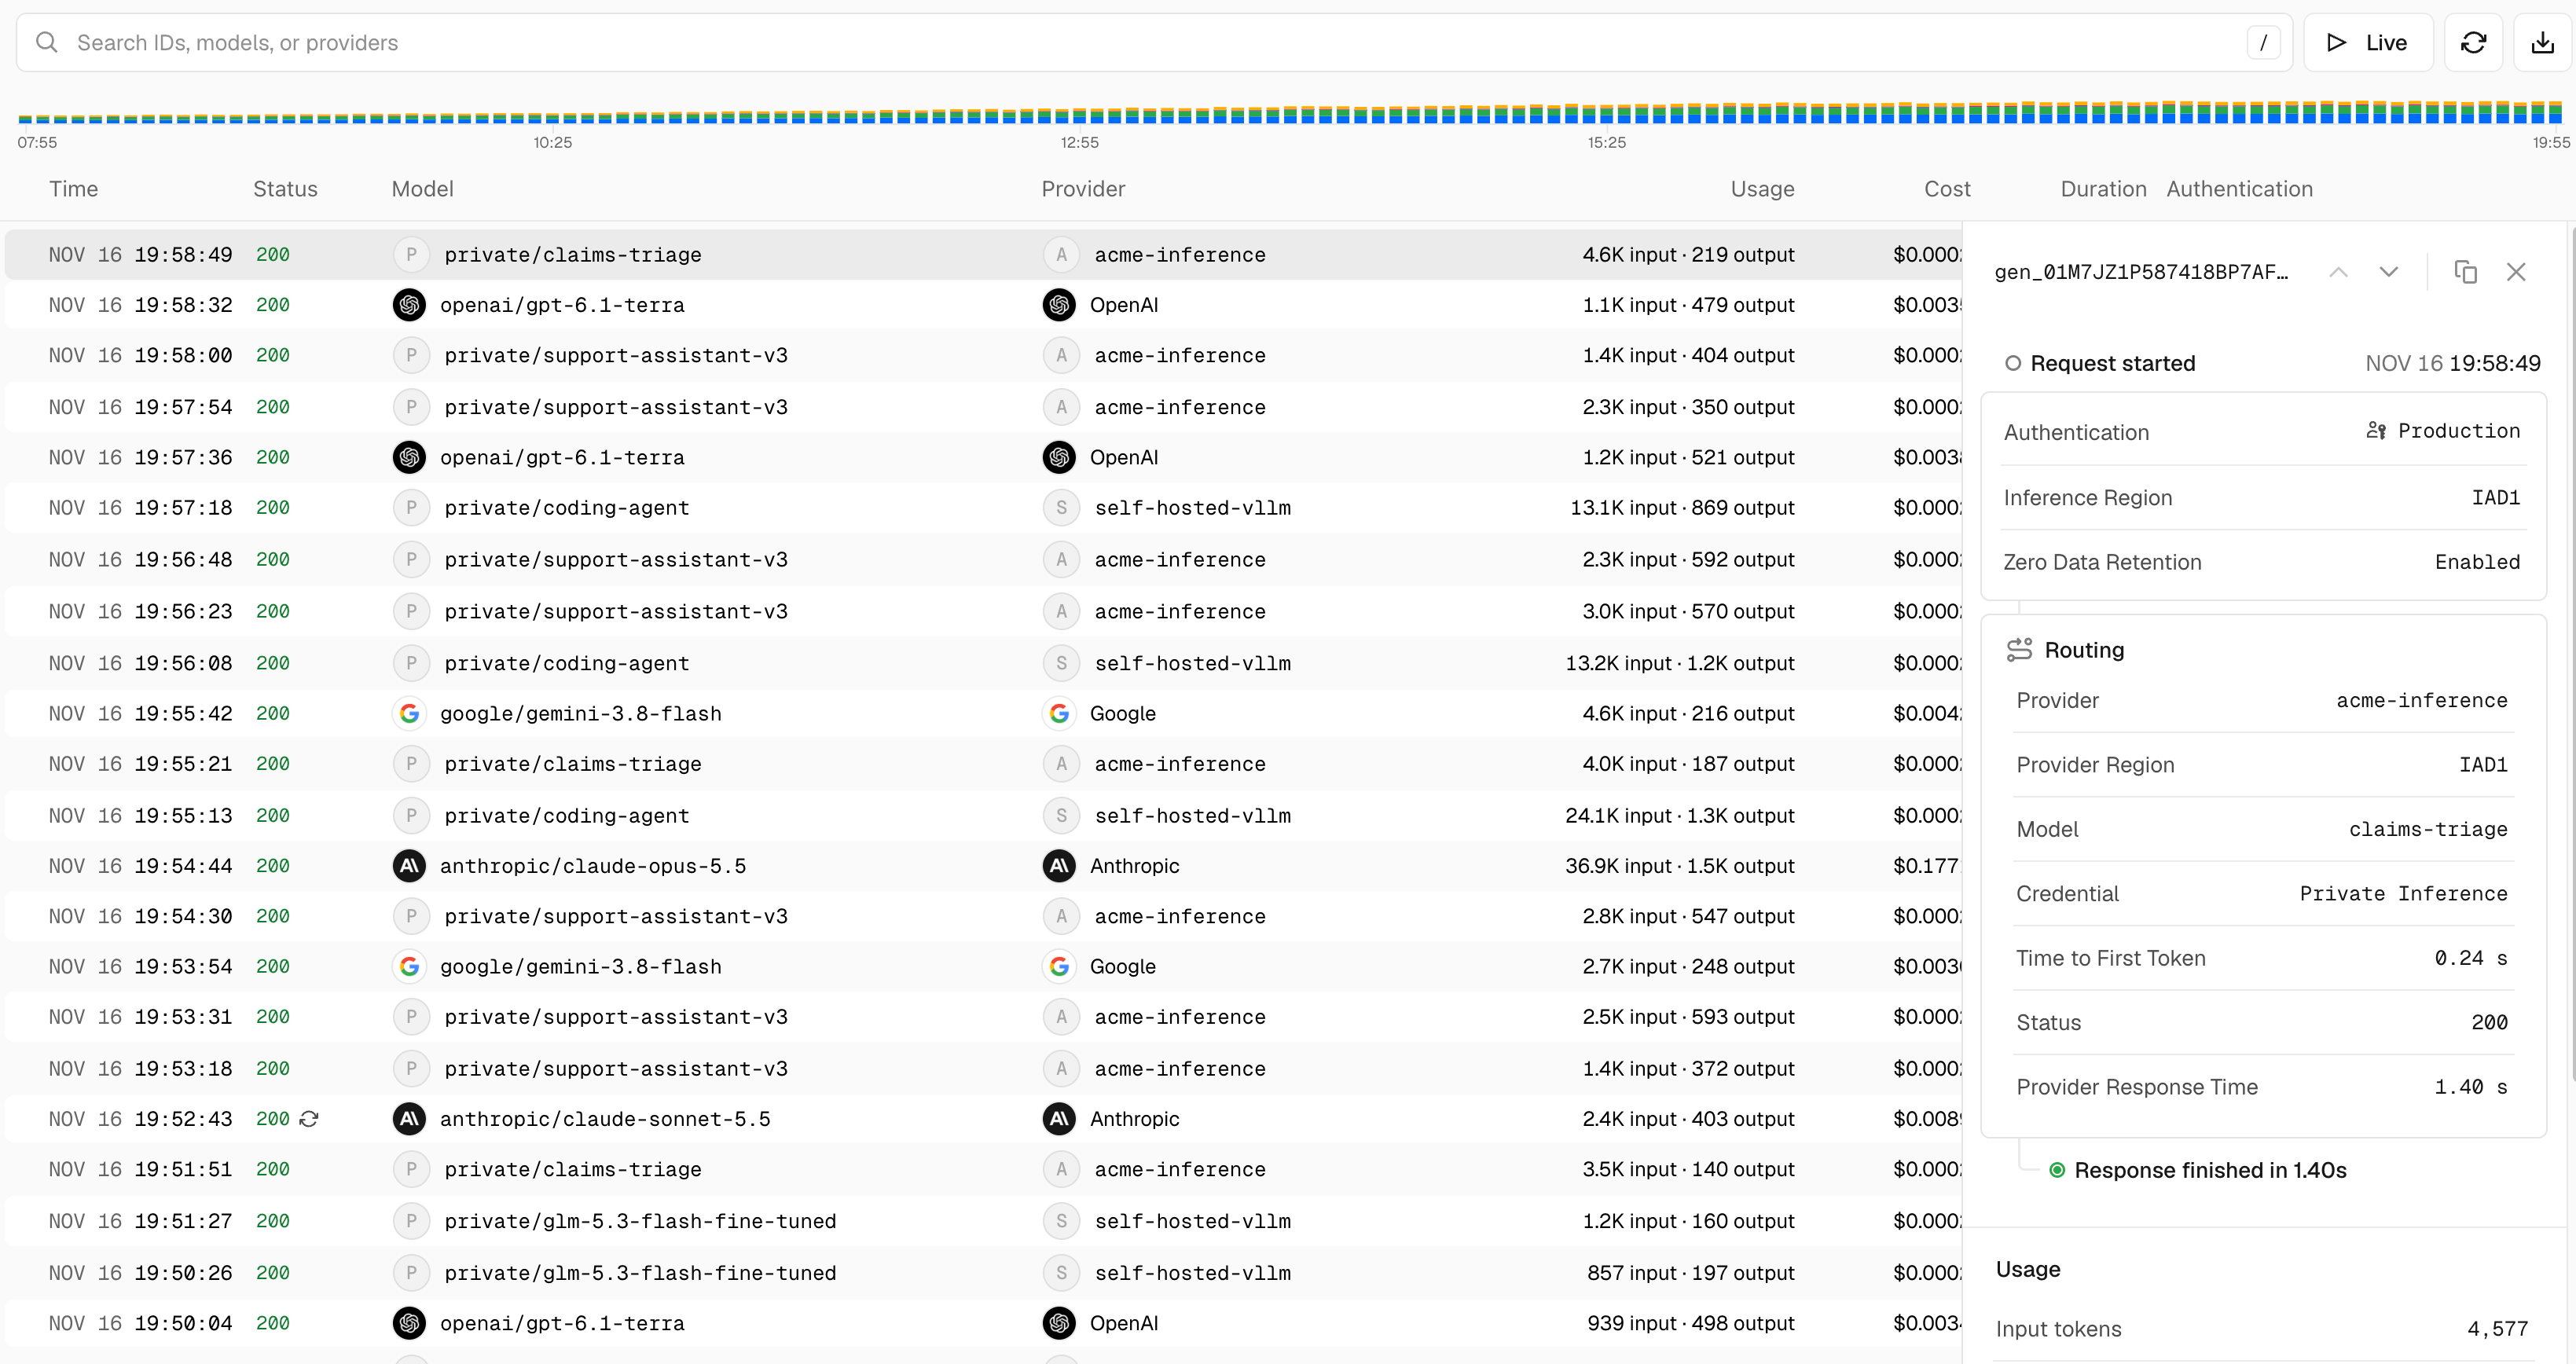
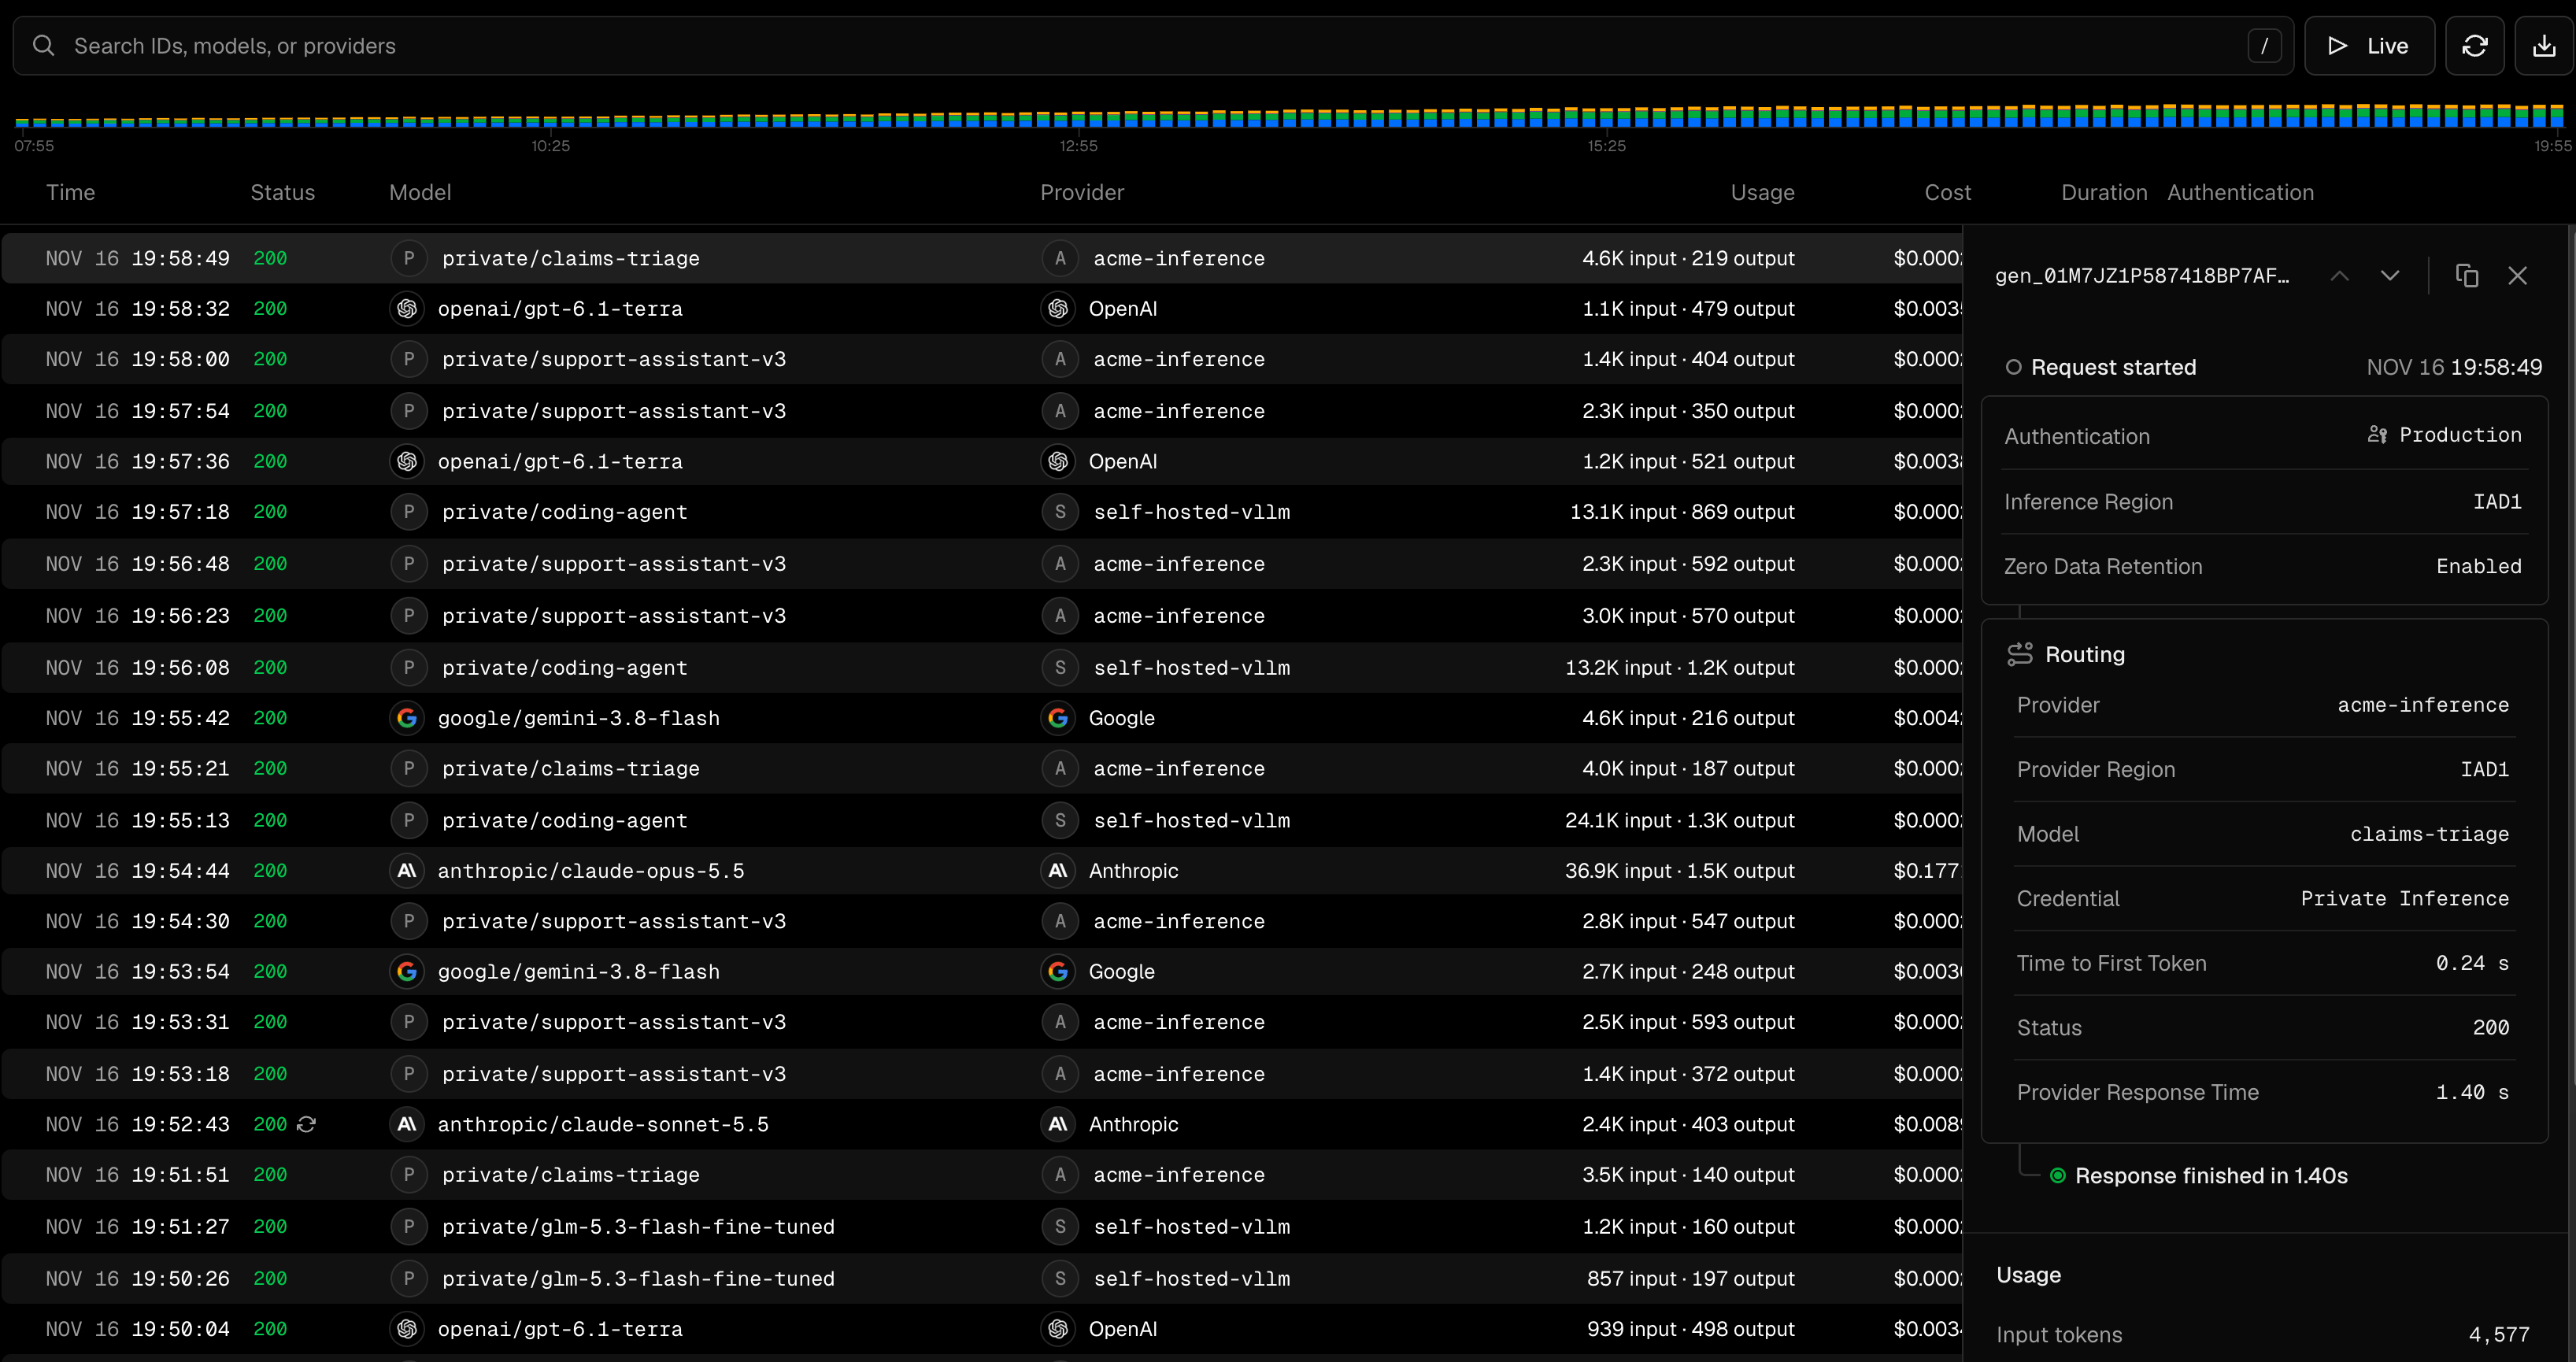
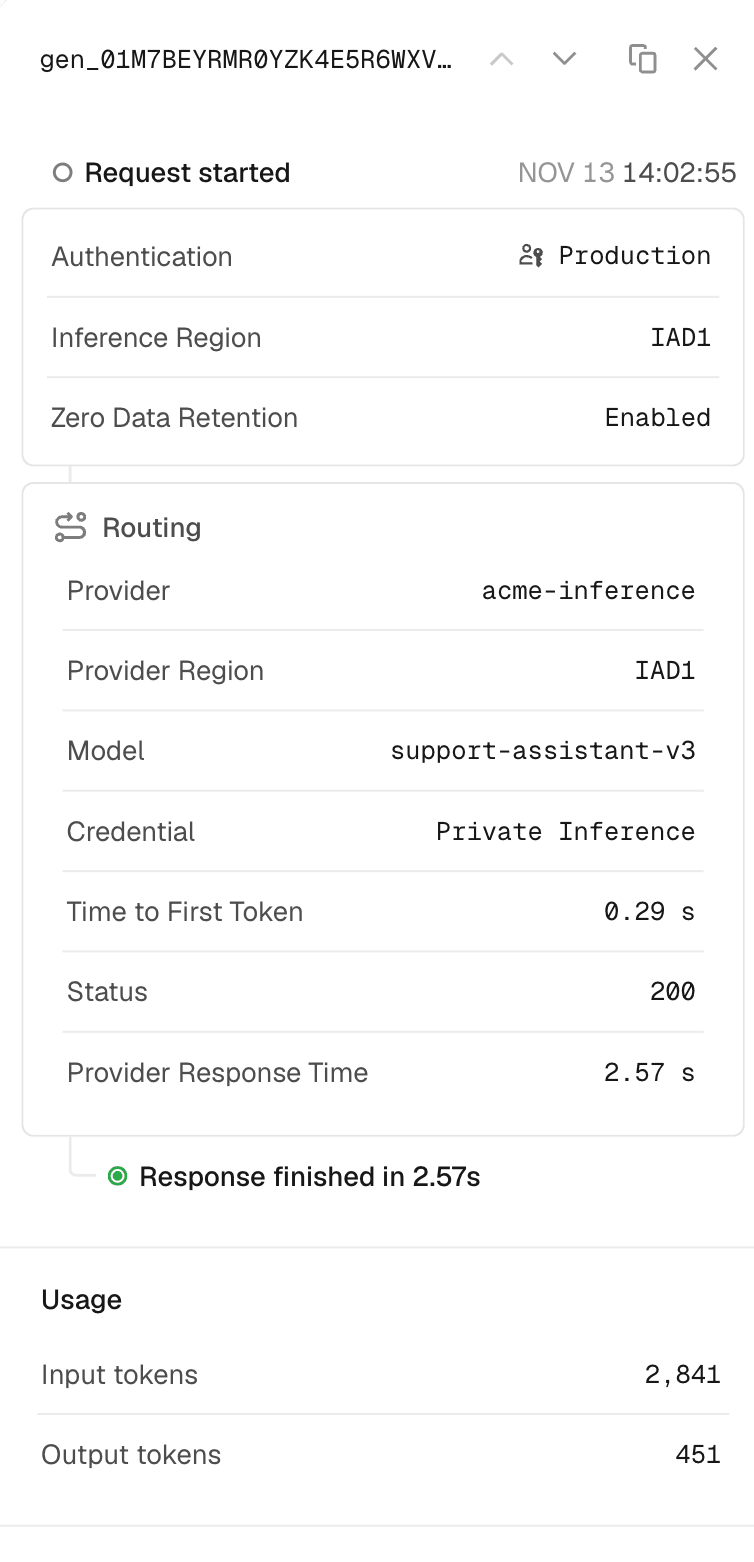
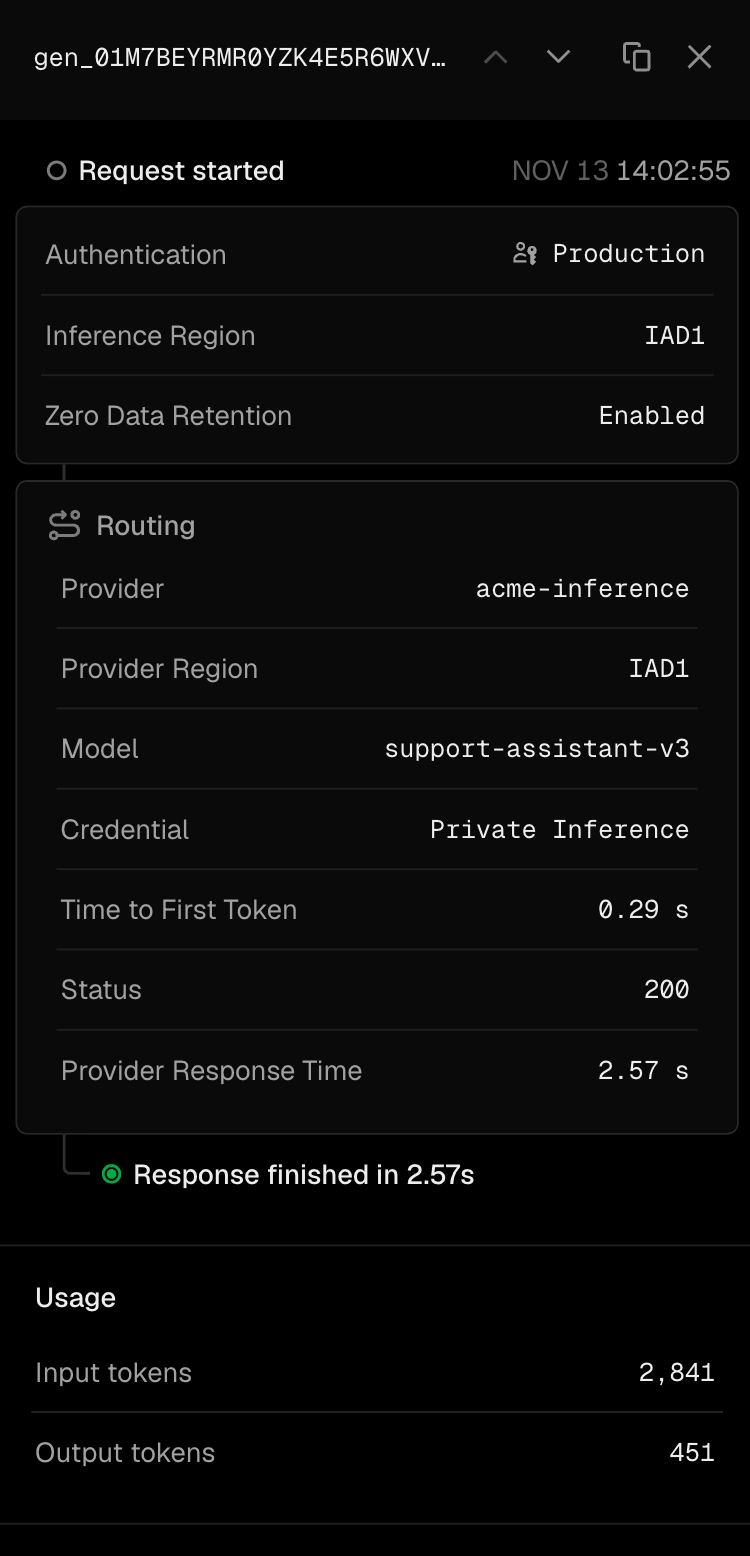
Monitor traffic together: View private model requests alongside catalog traffic in logs, trace drains, and custom reporting. Observability charts break down requests, tokens, and time to first token by private model.
Configure fallbacks: Optionally fall back to a catalog model if your private endpoint fails.
To get started, open the Private Inference page and add your endpoint as a private provider. Enter its base URL, select its API format, and add its credentials. Then add the models it serves.
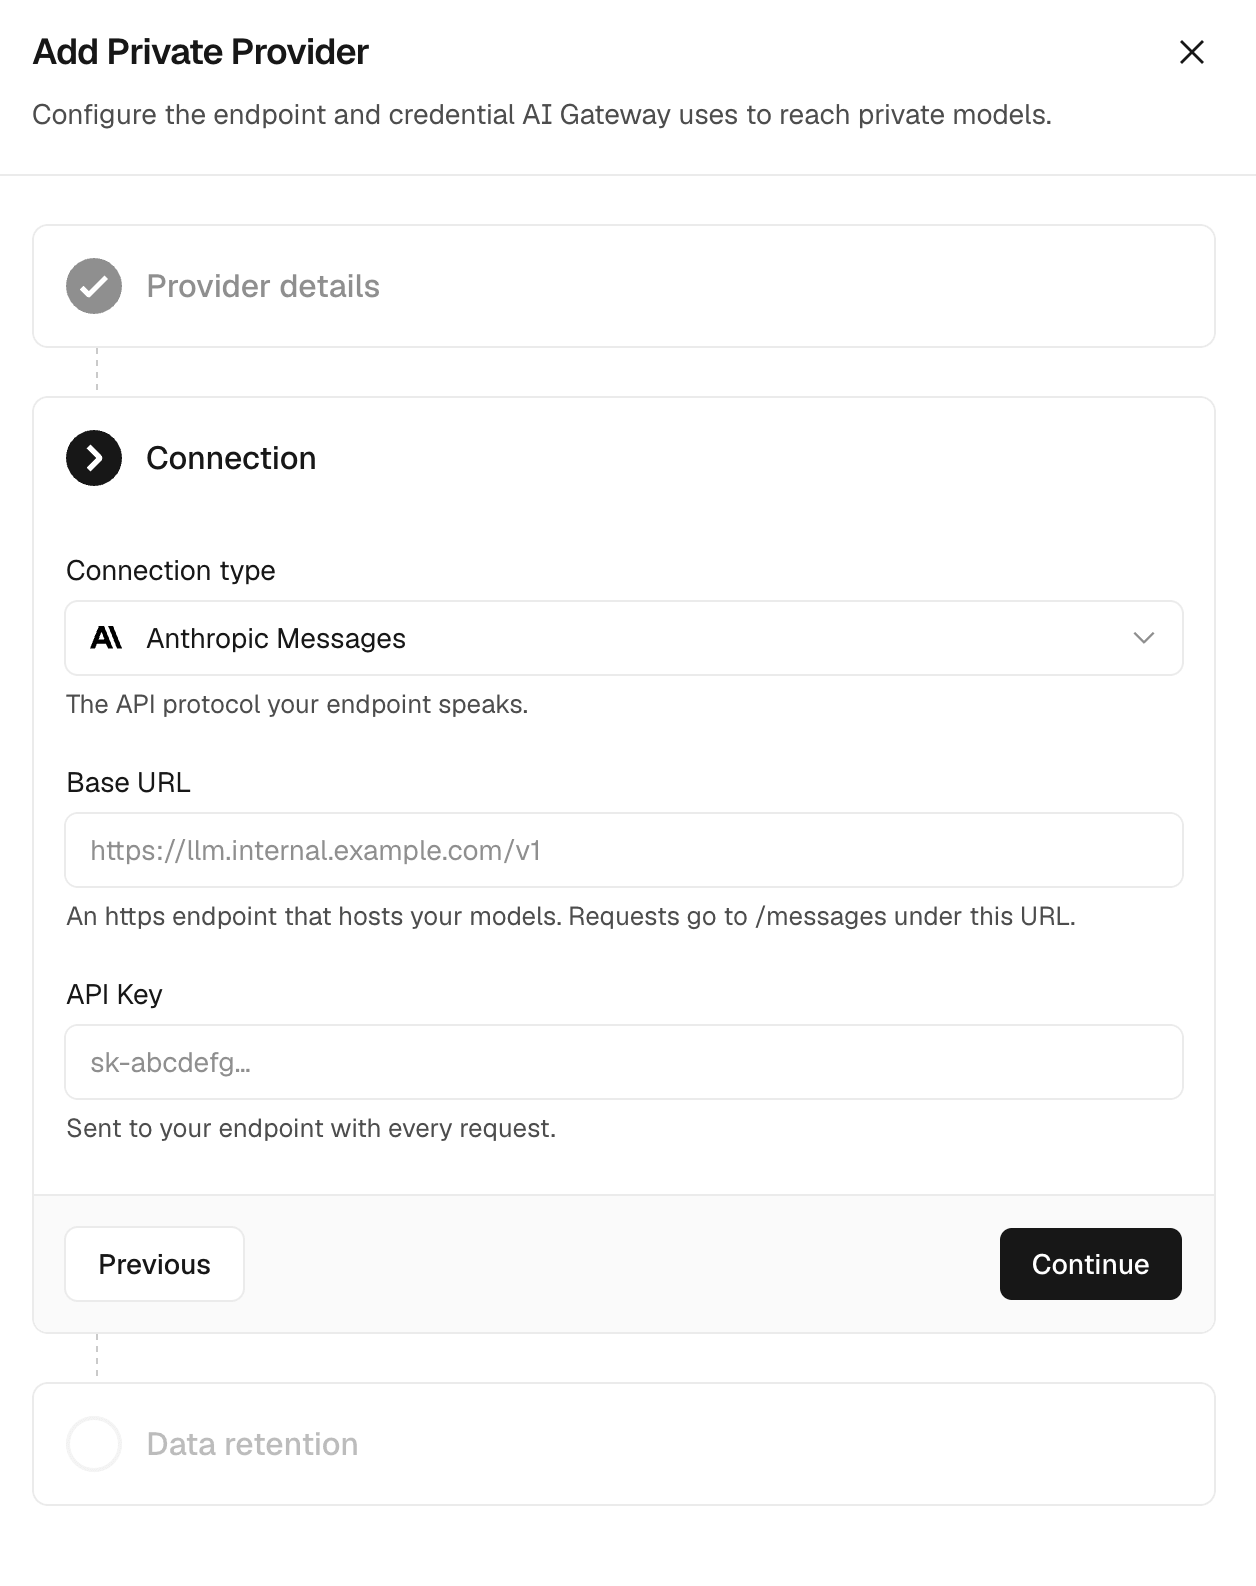
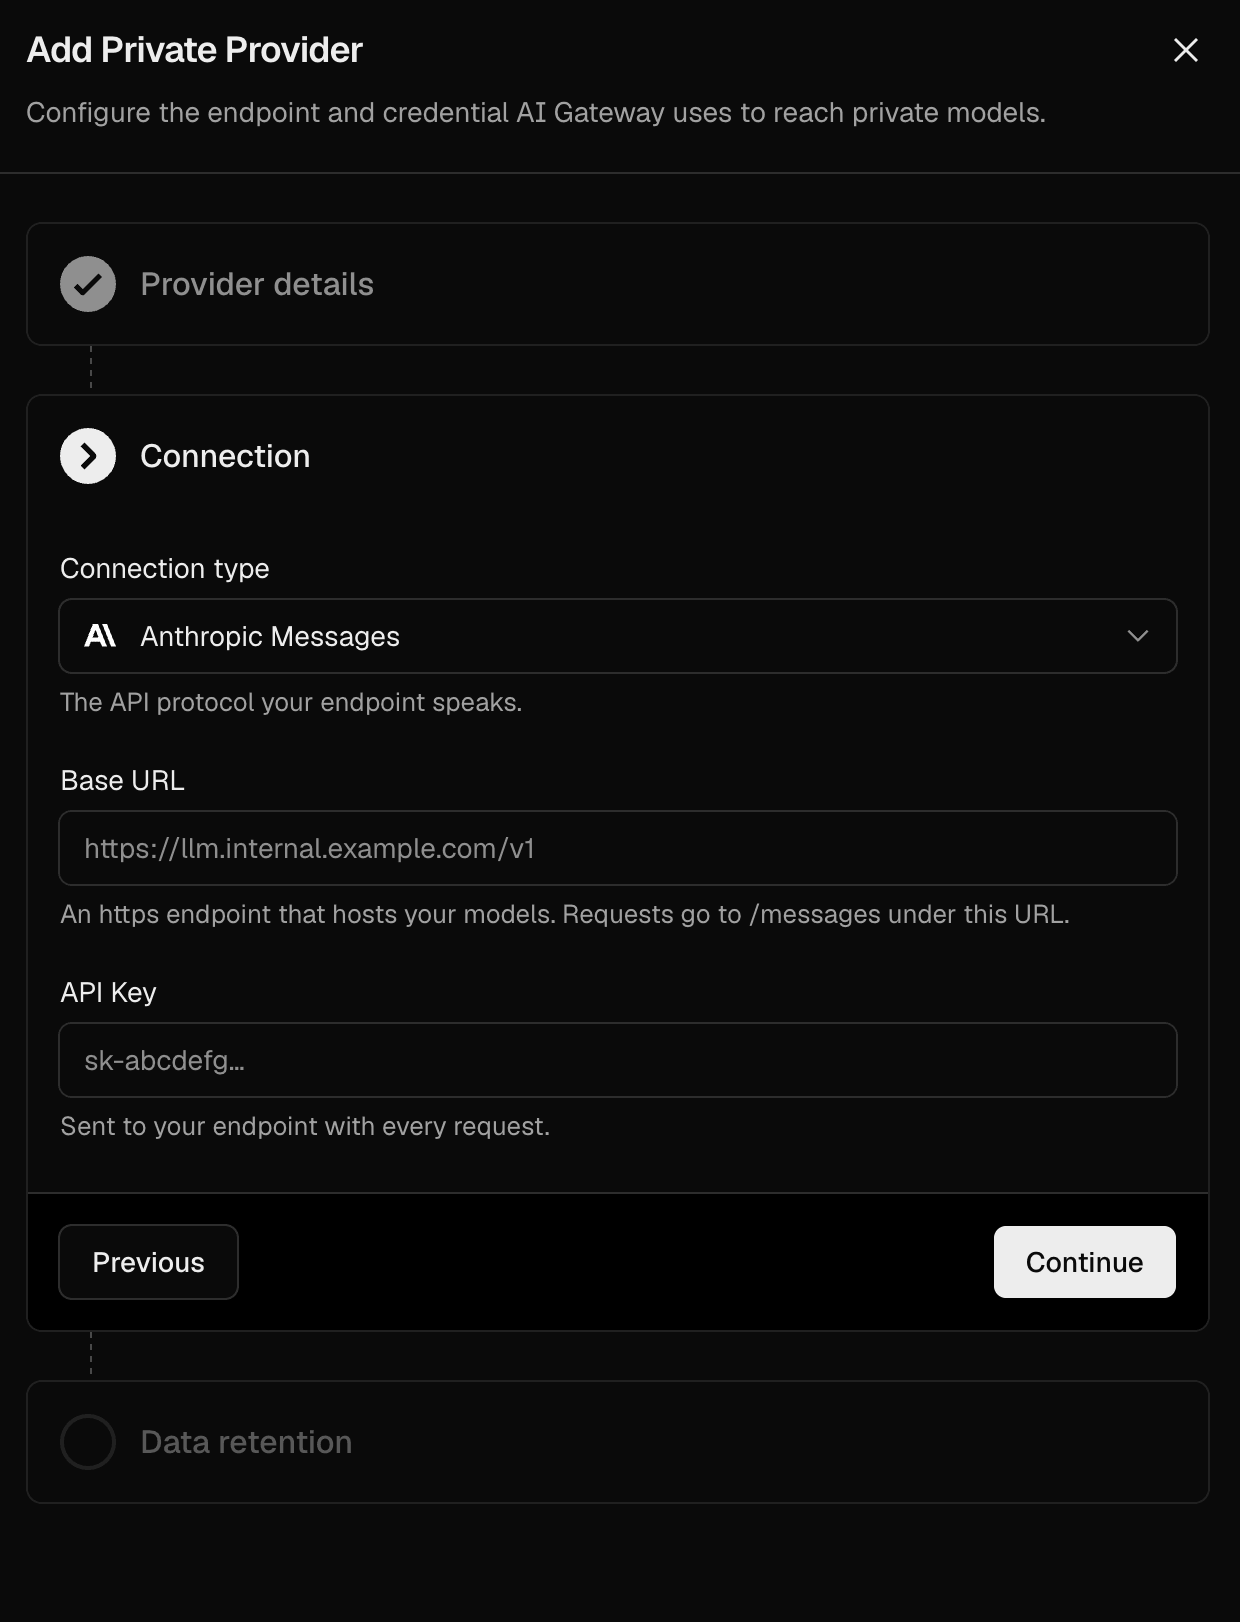
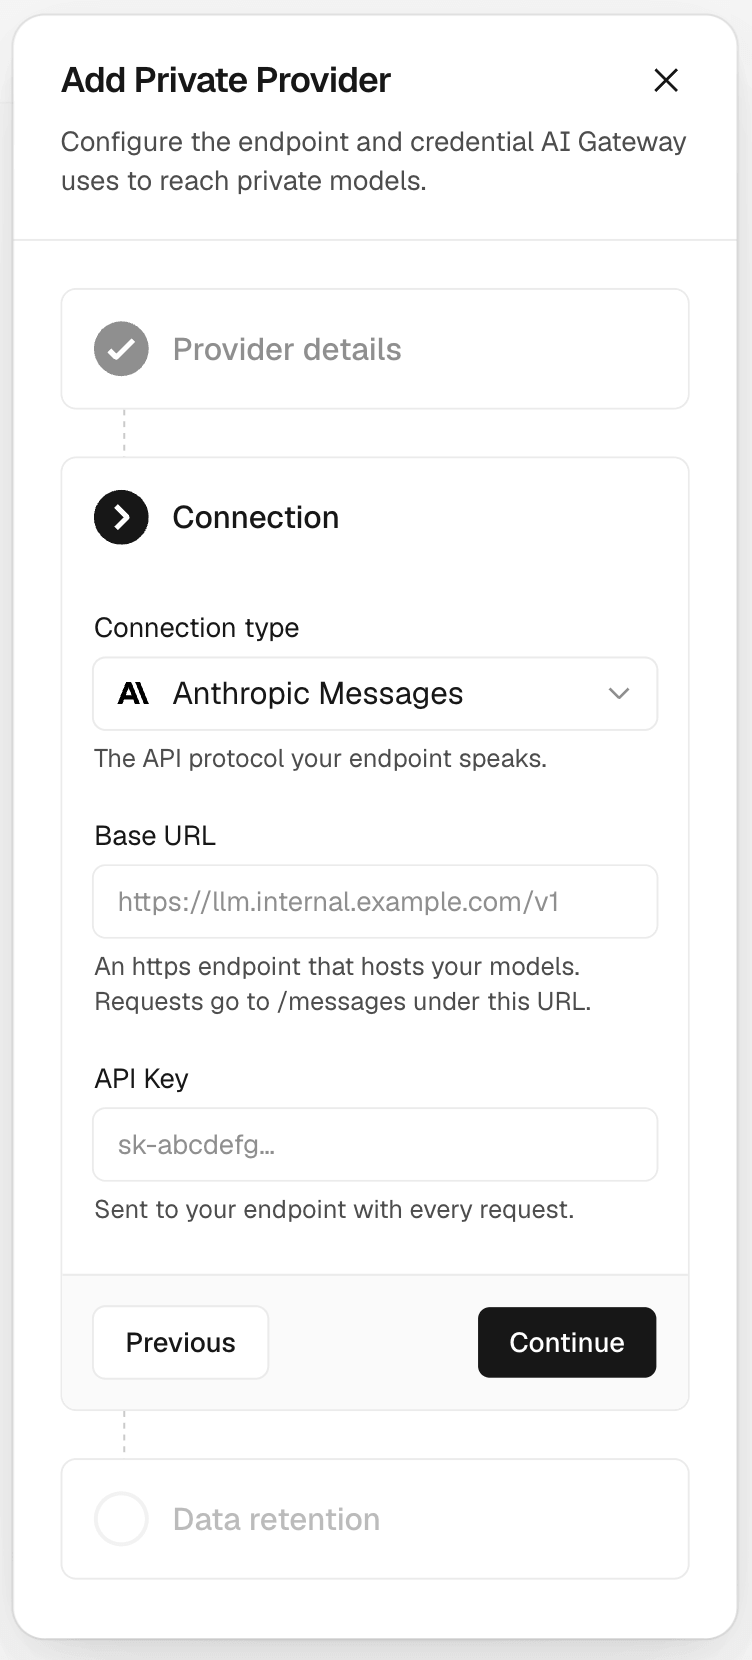
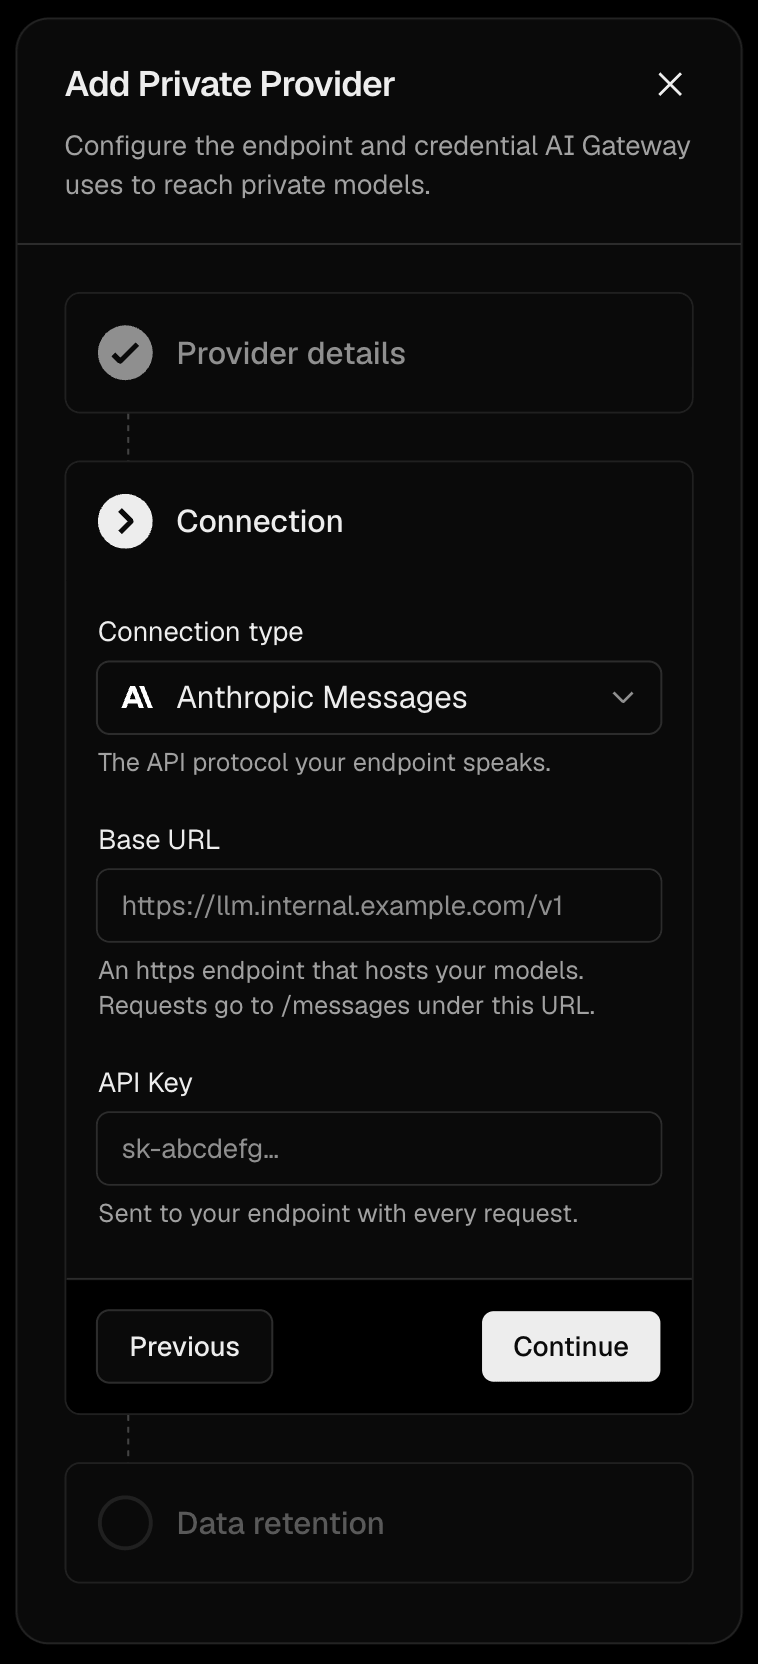
You can also register the provider and model with the Vercel CLI, version 65.16.0 or later:
# Connect your endpoint as a private providervercel ai-gateway private-inference providers create acme-vllm \ --base-url https://vllm.example.com/v1
# Expose the endpoint's model as private/support-fine-tunevercel ai-gateway private-inference models create support-fine-tune \ --provider acme-vllm \ --api-model acme/support-llama-ftCall the model using its private/<slug> ID:
import { streamText } from 'ai';
const result = streamText({ model: 'private/support-fine-tune', prompt: 'Draft a reply to a customer who was charged twice.', providerOptions: { gateway: { // Optional fallback to a catalog model models: ['anthropic/claude-sonnet-5.5'], }, },});
for await (const text of result.textStream) { process.stdout.write(text);}Private model requests appear in AI Gateway logs alongside requests to catalog models.
Read the Private Inference documentation for supported model types, requirements, and billing details.
Reference Architecture
Choose a stack and work through the decisions behind it, with curated documentation, guides, templates, and courses to help you build.
- Agent stack: Build and operate agents with models, tools, and durable workflows.
- Web applications: Choose rendering, data, authentication, and caching approaches.
- Backends: Choose a runtime, connect services, and run background work.
Build with prompts
Build an app, extend an agent, or improve your project with ready-to-use prompts for your coding agent.