How Do I Cut My Token Bill with Caching?
The Taco Tuesday assistant sends the full menu and operating instructions with every order. Those repeated input tokens can become a significant part of the request cost even when the content has not changed.
Prompt caching lets supported providers reuse that stable prefix instead of charging the full input rate each time.
Outcome
Enable automatic caching on the ordering assistant's model and prove, with token counts from two consecutive requests, that the second one read the menu and handbook from cache instead of paying full price.
Fast Track
- Add
providerOptions: { gateway: { caching: 'auto' } }to a call with a big stable prefix - Run the same request twice
- Compare
usage.inputTokenDetails.cacheReadTokens: zero the first time, nearly the whole prefix the second
Hands-on exercise
Build scripts/cache-check.ts with two identical requests and print the token details for each one.
Requirements:
- Use an Anthropic model (
anthropic/claude-sonnet-4.6), because Anthropic needs the explicit markers, which makes the Gateway's work visible - Send
TRUCK_INSTRUCTIONSandTRUCK_HANDBOOKfromlib/menu.tstogether asinstructions, plus a short customer question - Set
caching: 'auto'underproviderOptions.gateway - After each call, print
inputTokens,cacheReadTokensfromusage.inputTokenDetails, and the actual cost fromgateway.cost
Caching requires at least two requests to demonstrate a hit. The first request writes the cache entry and may carry a write premium; the second request can read it at the cached-input rate.
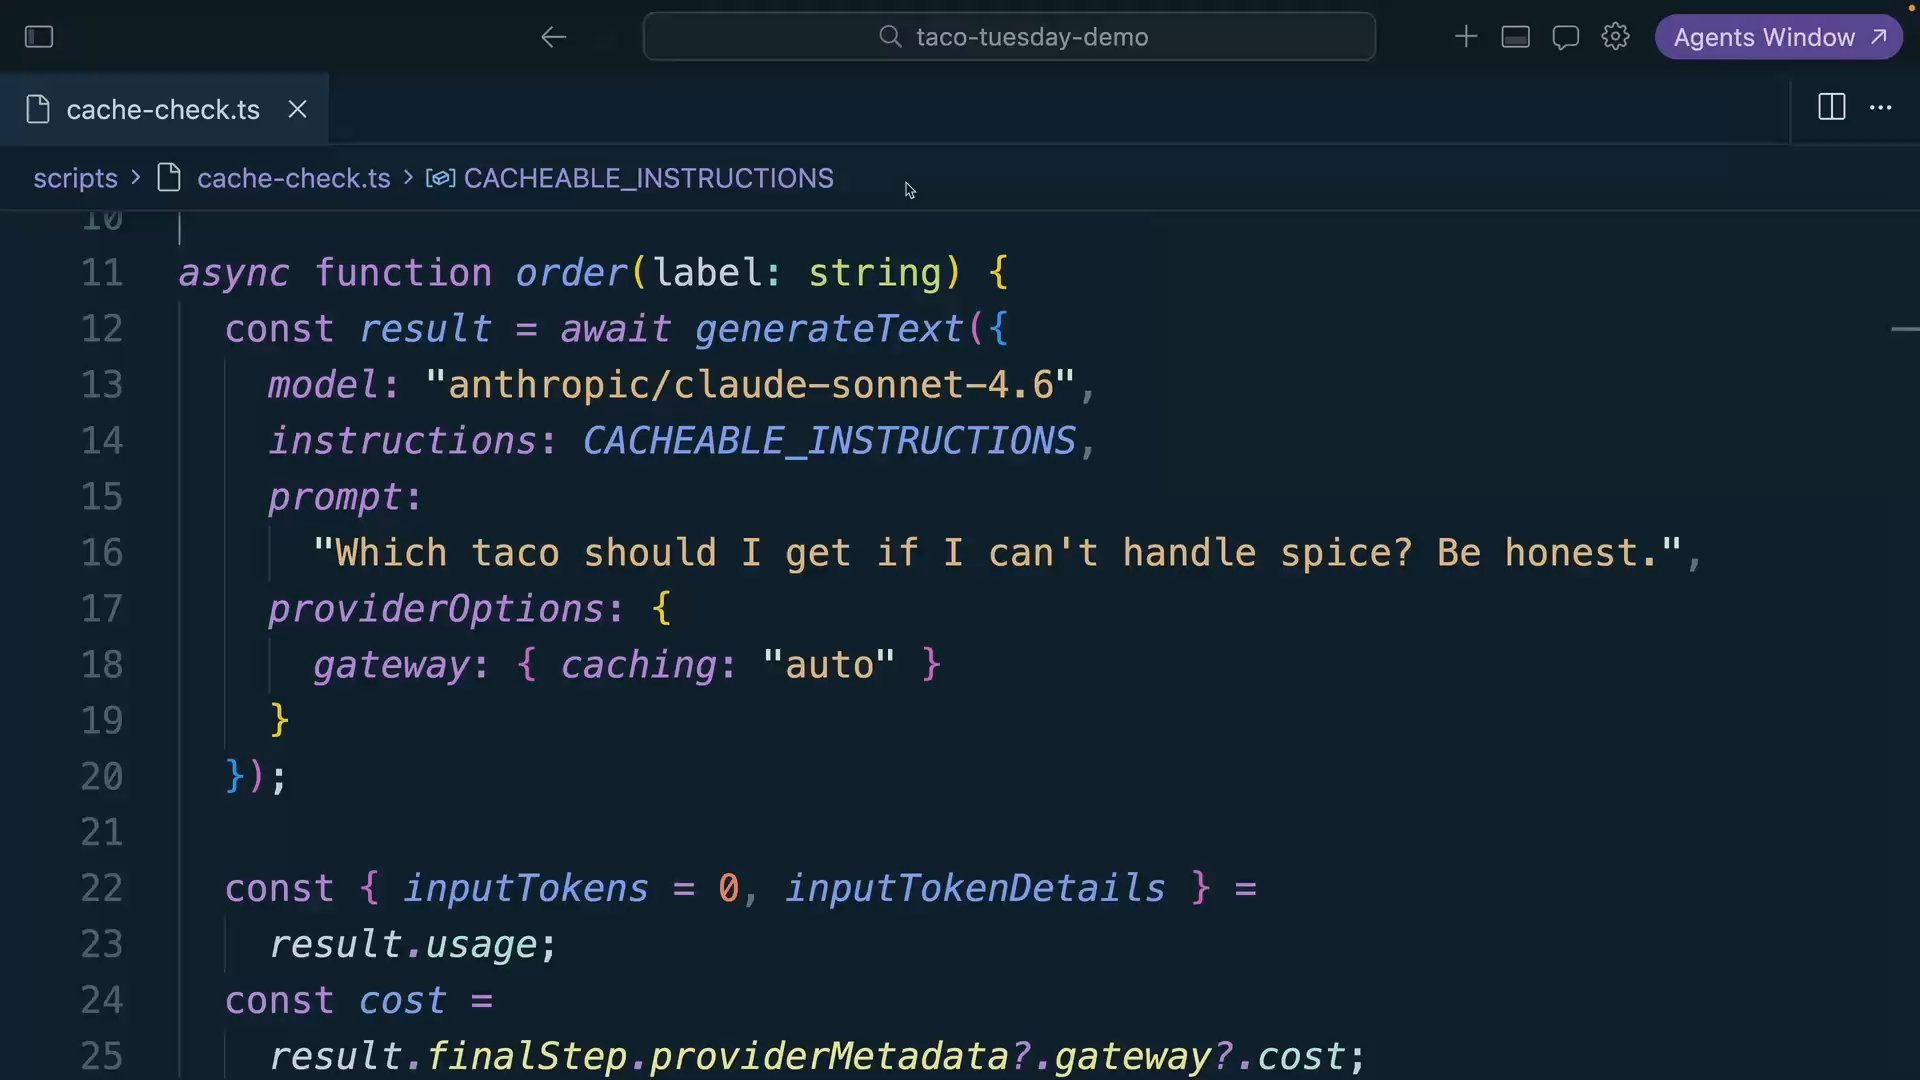
Why the handbook? Let's try the menu by itself first. Set instructions: TRUCK_INSTRUCTIONS and run the script:
--- Request 1 ---
Input tokens:      612
Cache read tokens: 0
Cost:              $0.002214

--- Request 2 ---
Input tokens:      612
Cache read tokens: 0
Cost:              $0.002229
Two identical requests and zero cache reads, with nothing in the output to say why. This is expected. Every model has a minimum cacheable prompt length, and 612 tokens of tacos falls short of Claude Sonnet 4.6's. Anthropic processes a shorter prompt without caching and returns no error, so caching: 'auto' adds its markers and the provider quietly ignores them.
The truck handbook fixes that. It holds the allergen notes and catering rules the assistant needs anyway, and it pushes the stable prefix well past the threshold:
instructions: `${TRUCK_INSTRUCTIONS}\n${TRUCK_HANDBOOK}`,Try It
pnpm cache-check--- Request 1 ---
Input tokens: 1603
Cache read tokens: 0
Cost: $0.006911
--- Request 2 ---
Input tokens: 1603
Cache read tokens: 1589
Cost: $0.001406
The first request costs more than an uncached one would, because it paid the cache-write premium. Request 2 read nearly the whole prefix from cache and came in at about a fifth of that price.
Three issues you may encounter:
cacheReadTokens is 0 on both requests, every time. The prefix is probably shorter than the model's minimum cacheable length. Check that TRUCK_HANDBOOK is part of instructions, and check the current minimums if you switched models, because they differ by model.
cacheReadTokens is 0 on the second request. Check the provider's current cache lifetime and confirm that the stable prefix is byte-identical. A timestamp or request-specific value in the instructions prevents a prefix match.
The second request used another provider. Cache entries live with a provider, so changing providers can produce a miss. Pin cache-sensitive traffic when consistency matters, as shown in lesson 1.7.
Commit
git commit -m "feat(caching): enable automatic prompt caching for the menu prefix"Done-When
scripts/cache-check.tsruns two requests and prints both receipts- Request 2 shows
cacheReadTokenscovering most of the instructions and handbook - Request 2's actual cost is visibly smaller than request 1's
- You can say when
caching: 'auto'would lose money (one-shot traffic)
Solution
import { generateText } from "ai";
import { TRUCK_HANDBOOK, TRUCK_INSTRUCTIONS } from "../lib/menu";

async function order(label: string) {
  const result = await generateText({
    model: "anthropic/claude-sonnet-4.6",
    instructions: `${TRUCK_INSTRUCTIONS}\n${TRUCK_HANDBOOK}`,
    prompt: "Which taco should I get if I can't handle spice? Be honest.",
    providerOptions: {
      gateway: { caching: "auto" },
    },
  });

  const { inputTokens = 0, inputTokenDetails } = result.usage;
  const cost = result.finalStep.providerMetadata?.gateway?.cost;

  console.log(`--- ${label} ---`);
  console.log(`Input tokens:      ${inputTokens}`);
  console.log(`Cache read tokens: ${inputTokenDetails?.cacheReadTokens ?? 0}`);
  console.log(`Cost:              $${cost}`);
}

await order("Request 1");
await order("Request 2");
The second request's token metadata tells us whether the provider reused the prefix and how that changed the cost.
Related Questions
Was this helpful?